

Founding engineer. Building agent harnesses and dev tools
Australia
Joined August 2022
- Tweets766
- Following110
- Followers209
- Likes622


the ultimate trick to eliminate claudish english, ask claude to respond at a specific CEFR english level (A1 → C2), the difference is staggering
20

Eugene Oldman retweeted

my spidey senses are telling me the labs are, as we speak, using unguardrailed versions of their unreleased models to systematically reverse-engineer ALL of the internet’s software, apps, and games, then feeding the reconstructed source code straight into their training pipelines while simultaneously building guardrails to ladder-pull the rest of us
that's A LOT of room for customization! the age of malleable software is here, everything is just one prompt away


the new version of @buzzdotxyz is built on top of an excellent plugin architecture, my mind is 🤯
so many ideas...
2
113
buzz is so back haha
the new version of @buzzdotxyz is built on top of an excellent plugin architecture, my mind is 🤯
so many ideas...
43

jev++

You already gave the LLM the answer. So why is it writing it out from scratch?
Introducing a new AI model architecture: Constrained Decoding Models (CDMs)
LLMs were built to write. Most production workloads just need an answer: fast, consistent, and affordable.
CDMs are purpose-built for 1 task each. They read your input once and skip the token-by-token generative loop that makes LLMs slow and expensive.
Not just a decision model, but a family of 3 CDMs live today:
• Classify: define your labels and get back a calibrated probability + reason for each. Used for routing, tagging, and intent detection.
• Extract: describe the entities in natural language and get back well-formed JSON with confidence scores + citations. Used for web scraping, document processing, and PII redaction.
• Summarize: pass in long text, images, or PDFs and get back a consistent summary under 1,000 tokens. Used for context compaction, metadata generation, and transcript digests.
Built for production:
• 1M tokens of multimodal (text + image) input, 31x larger than Jev
• 77.2% on DecisionBench vs Jev's 72%
• 200x faster, 467x cheaper than frontier LLM APIs
• $0.05/M input tokens. Output is free (yes, even for summarize)
Live on your favorite platforms today:
@OpenRouter @vercel_dev @LiteLLM @LangChain @TrustedRouter @itsArthurAI @useRouterPlus
Get 50M input tokens for free (for the first 50 hours) at link below 👀
1
1
59
if you are on max plan this will let you experiment with claude models on any custom harness (pi, prime agent, you name it) for free (up to the limit ofc lol)

We’re rolling out monthly Claude Platform API credits for Max and Team plans:
Max 5x: $100
Max 20x: $200
Team: up to $500, pooled
Works on any model, including Haiku 5.5, in your code or third-party harnesses.
How it works and full terms: support.claude.com/en/articl…

54


tested how many questions one jev request takes
500 caught all 50 wrong answers
1000 missed 7 of 100
1500 missed 8 of 150
2000 rejected, over the 64k token limit


a kimi swarm finishes 300 tasks at the same moment, and then the pipeline checks them in single file
300 results / 300 review calls / the same brief and rules sent 300 times
nobody draws that loop on the architecture diagram, but at 300 agents it quietly becomes the slowest stage of the run
the fix is almost boring: send jev the shared context once and ask one typed question per result
one request comes back with 300 verdicts, each with a confidence you can threshold
only the misses go back to kimi: 300 → 29 → a handful → 0, one call per round
the swarm was never the bottleneck, the review line behind it was
2
153
I'm not surprised this is happening, given the state of management in big orgs (especially where engineering isn't a core org), where everything is reduced to performance metrics that no longer work in a world where ai writes code and engineers have become validators

I am done with this shit. It is over. The state of engineering right now is horrible. It has been half a month since I started a new role at a big company. Nobody knows anything here. The specs, code, tests, PRDs, tickets, resolution of those tickets, reports, etc., everything is made by Claude Code. Nobody on my team likes this. They are being forced to ship as much as they can. I have heard multiple times from higher management that pushing code is not a bottleneck, so why are we slow? People are working 12 to 13 hours a day just to press enter. Nobody is reading anything. Humans in corporate are doing nothing on their own. Everyone, literally everyone, from an L1 to an L7 engineer here is doing the same thing. Talk to Claude. There is no sense of victory. Nobody is resolving bugs. In reality, nobody is thinking anymore. Everything is done by LLMs. It is so soul-sucking. I would not mind it, to be honest, if we were at least given the time to check out the code and see what is going where. But no, the goal is to just ship. No matter what happens.
2
240
LLM output should serve to present options with pros and cons so humans can make their own decisions, rather than making decisions for them, that said, this isn't how most people use these tools, many outsource their thinking and decision making to a tool trained to produce the best average output for a given input, packaged in confidently helpful prose
1
1
58
Jev from @typesafeai lets you build self-evolving classifiers
Save this, use it in your prod app: track what falls into "other" and let an LLM turn those cases into new categories
engineering is so back

After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
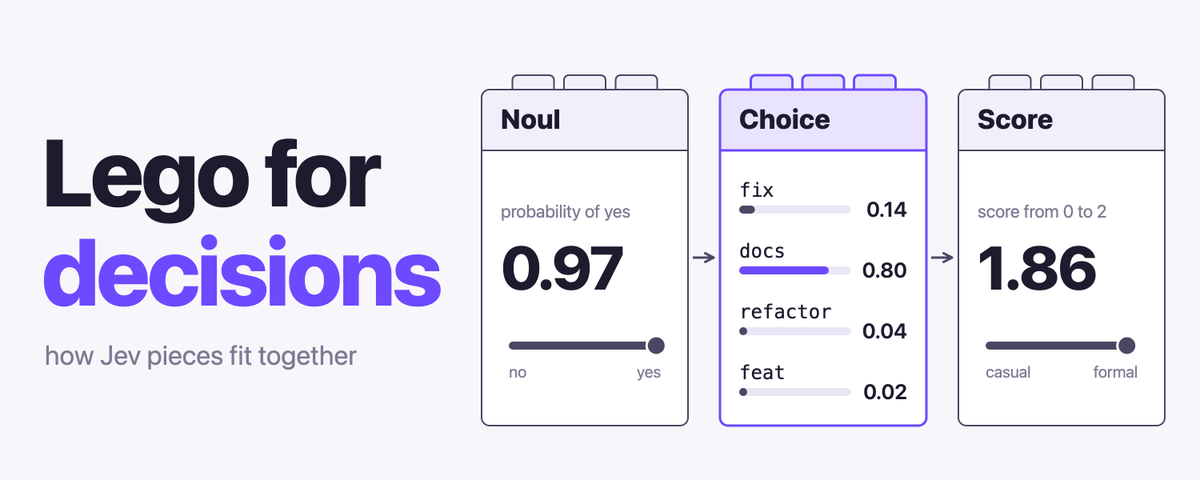
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
408
to finally teach us how to distinguish vibe coders from software engineers, the universe gave us @typesafeai
Eugene Oldman retweeted

After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution

