

Nerds taming the dragon with SCALE, our framework for compiling CUDA codebases for AMD and NVIDIA GPUs, with support for more accelerated platforms coming soon.
483 Green Lanes London England
Joined September 2025
- Tweets394
- Following56
- Followers359
- Likes191




SCALE has grown well past a compiler toolkit. Here's what we're bringing to booth 252 at SC26.
· Performance. SCALE is way faster than it was a year ago. Come and see how far it has come.
· The most agent-friendly GPU profiler ever built. It packages all profiling data in a standard format your coding agent can read, and that opens in the profiler tools you already use.
· SCALE-clangd. Errors flagged in the editor, before a full compile: fewer failed builds for you, fewer wasted tokens for your agent.
And ask us about SCALE-CPU, our prototype for CUDA code on CPUs.
📍 Chicago, booth 252
📅 Exhibition floor open November 17-19
Book a time with our team: meetings-eu1.hubspot.com/rub…

70
𝗦𝗖𝗔𝗟𝗘 𝟭.𝟳.𝟱 𝗶𝘀 𝗼𝘂𝘁, and it's the biggest step forward SCALE has ever taken.
· It's much faster, everywhere. CPU-side overheads are way down and kernels run faster. On AMD RDNA3 GPUs, most kernels run about twice as fast as with SCALE 1.7.4.
· Many more workloads run as they are. This release brings more fixes than any before it. The changelog is… long. We are okay, thanks for asking.
· More of CUDA is there. We added more new APIs than in any previous release, from NVIDIA's libraries for FFTs, linear algebra, sparse matrices and image processing to surface objects.
And we're not slowing down. Come and see for yourself at booth 252, SC26 in Chicago. The exhibition floor is open November 17-19.
Download SCALE 1.7.5, build your CUDA code with it, and tell us how it went on Discord.
Full release notes: docs.scale-lang.com/stable/m…

1
2
131
HPC went multi-vendor. Most software didn't.
Data centres now run AMD and NVIDIA GPUs side by side, and most code can't take advantage of that. It doesn't have to be that way. How? Come talk with us at SC26 in Chicago.
📍 𝗕𝗼𝗼𝘁𝗵 𝟮𝟱𝟮
📅 Exhibition floor open November 17-19
SCALE compiles unmodified CUDA (and soon HIP) code natively for AMD and NVIDIA GPUs. One codebase, both vendors.
Book a time before the floor fills up: meetings-eu1.hubspot.com/rub…

1
83
A ten-year-old NVIDIA GPU is, in many ways, 𝗺𝗼𝗿𝗲 𝗱𝗶𝗳𝗳𝗲𝗿𝗲𝗻𝘁 from today's NVIDIA GPUs than a current AMD GPU is.
CUDA code has absorbed that gap for twenty years. Teams don't rewrite their codebase for every new generation. The compiler takes the same source and builds it for hardware that has changed radically underneath it.
So the distance between vendors was never the hard part. Compilers already cross bigger distances than that, every generation. What was missing was a compiler that crosses the vendor line too.
That is what SCALE is: unmodified CUDA code, compiled natively for AMD and NVIDIA GPUs.
𝗖𝗨𝗗𝗔 𝗰𝗼𝗱𝗲 𝗮𝗹𝗿𝗲𝗮𝗱𝘆 𝗿𝘂𝗻𝘀 𝗼𝗻 𝘃𝗲𝗿𝘆 𝗱𝗶𝗳𝗳𝗲𝗿𝗲𝗻𝘁 𝗵𝗮𝗿𝗱𝘄𝗮𝗿𝗲. 𝗪𝗲 𝘄𝗶𝗱𝗲𝗻𝗲𝗱 𝘁𝗵𝗲 𝗹𝗶𝘀𝘁.
Explore SCALE: scale-lang.com/?utm_source=t…

1
67
𝗦𝗖𝗔𝗟𝗘 𝟭.𝟳.𝟰 𝗶𝘀 𝗼𝘂𝘁.
Same CUDA code, same answers: single-precision maths now meets NVIDIA's documented error bounds. Fast-math division behaves as it does with nvcc, which can mean a very large speedup for division-heavy kernels. Occupancy fixes let code that sizes its own launches get more out of the GPU, and launches and 3D memory copies are faster too.
Download SCALE 1.7.4 for free, run it on your codebase, and tell us how it went on Discord.

Full release notes: docs.scale-lang.com/stable/m…
Join us on Discord: scale-lang.com/s/discord-li
2
36
The most useful thing a SCALE user can send us is a bug report.
The CUDA API is huge. Large-scale projects depend on both documented and undocumented behaviours. The real target isn't described by the manual, it emerges when we try to run real workloads.
So what users actually hit decides which parts of the API we cover next and which fixes ship first.
If SCALE fails to build your code, gives wrong results, or runs slower than it should, tell us what broke and where on Discord. It moves your problem up the list.
𝗬𝗼𝘂𝗿 𝗳𝗮𝗶𝗹𝗲𝗱 𝗯𝘂𝗶𝗹𝗱 𝗶𝘀 𝗼𝘂𝗿 𝗿𝗼𝗮𝗱𝗺𝗮𝗽.

AMD Instinct™ GPUs are incredible. A single AMD Instinct™ MI355X sports 𝟮𝟴𝟴𝗚𝗕 𝗼𝗳 𝗛𝗕𝗠𝟯𝗘, 𝟴𝗧𝗕/𝘀 𝗼𝗳 𝗽𝗲𝗮𝗸 𝗺𝗲𝗺𝗼𝗿𝘆 𝗯𝗮𝗻𝗱𝘄𝗶𝗱𝘁𝗵 𝗮𝗻𝗱 𝟳𝟴.𝟲 𝗧𝗙𝗟𝗢𝗣𝘀 𝗼𝗳 𝗽𝗲𝗮𝗸 𝗙𝗣𝟲𝟰.
Put eight in a node and you have 2.3TB of HBM3E: enough to hold an entire frontier-scale model in memory on one machine. For accelerated HPC, it means bigger simulations resident on a single GPU, bandwidth-bound kernels with space to breathe, and serious double precision.
SCALE compiles supported CUDA code to run natively on it, cutting the effort required to move existing applications.
Our compiler is built to use what the hardware offers. One example: AMD GPUs can pass data between threads through DPP, hard-wired lane permutations that cost almost nothing. SCALE recognises the patterns in ordinary CUDA shuffles and maps them onto DPP automatically, so your code takes the fast path without a line of AMD-specific code.
The silicon was always capable. What held CUDA workloads back on AMD was getting the code there without leaving performance behind on the way. That is a compiler problem, and compilers can be fixed once for everyone.
We are now listed in @AMD's Instinct AI & HPC Software Ecosystem Program!
amd.com/en/ecosystem/isv/dat…

A hybrid GPU fleet only pays off if every part of it runs your code fast.
The best price-performance moves between vendors and hardware generations. Mixing accelerators is how you follow it.
The catch is the software. A second vendor usually means a second codebase, tuned to the same standard as the first. Every optimisation lands twice. Every release is validated twice. The engineering bill eats the hardware savings.
scale-lang.com removes that step. Your existing CUDA code compiles natively for AMD and NVIDIA GPUs, and the compiler does the tuning: novel optimisations that use each target's own hardware features, including ones that cannot be expressed in source at all.
On the Extended OpenDwarfs suite, unmodified CUDA code compiled with SCALE 1.7.3 is 𝗼𝗻 𝗽𝗮𝗿 𝘄𝗶𝘁𝗵 𝗛𝗜𝗣 𝗮𝗻𝗱 𝗻𝘃𝗰𝗰 𝗼𝗻 𝗮𝘃𝗲𝗿𝗮𝗴𝗲, and faster on about half the workloads (AMD MI300X and NVIDIA B300, September 2026).
𝗢𝗻𝗲 𝗰𝗼𝗱𝗲𝗯𝗮𝘀𝗲. 𝗘𝘃𝗲𝗿𝘆 𝗮𝗰𝗰𝗲𝗹𝗲𝗿𝗮𝘁𝗼𝗿 𝗶𝗻 𝘁𝗵𝗲 𝗳𝗹𝗲𝗲𝘁 𝗲𝗮𝗿𝗻𝗶𝗻𝗴 𝗶𝘁𝘀 𝗸𝗲𝗲𝗽.
Benchmarks: scale-lang.com/?utm_source=t…
The fairest way to compare GPU toolchains is to hand them the same workload.
That is the idea behind Extended OpenDwarfs, the benchmark suite built by our colleague Beau Johnston: 16 benchmarks spanning 13 Berkeley dwarfs, each written in CUDA, HIP and OpenCL, with every run checked for correctness.
Beau has now turned it on scale-lang.com. The CUDA code is compiled with SCALE and measured against native HIP on AMD and nvcc on NVIDIA, on systems from AMD Vega to NVIDIA Blackwell.
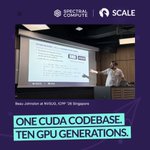
The result is a peer-reviewed paper, 𝘚𝘤𝘢𝘭𝘪𝘯𝘨 𝘵𝘩𝘦 𝘌𝘹𝘵𝘦𝘯𝘥𝘦𝘥 𝘖𝘱𝘦𝘯𝘋𝘸𝘢𝘳𝘧𝘴, which Beau presented in Singapore at the NVIDIA Supercomputing User Group (NVSUG) workshop at ICPP '26. Code and raw data are open, so anyone can rerun it.
The same suite runs our newest benchmarks too: with SCALE 1.7.3, unmodified CUDA code is 𝗼𝗻 𝗽𝗮𝗿 𝘄𝗶𝘁𝗵 𝗛𝗜𝗣 𝗮𝗻𝗱 𝗻𝘃𝗰𝗰 𝗼𝗻 𝗮𝘃𝗲𝗿𝗮𝗴𝗲, and faster on about half the workloads.


You shouldn't have to pick a GPU vendor up front. And your codebase shouldn't pick one for you.
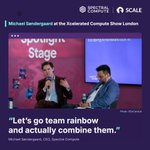
That was our CEO @SpectralMichael's point on stage at the The Xcelerated Compute Show in London, in a fireside chat with @dcdnews's Vlad - Gabriel Anghel.
He calls it team rainbow 🌈: rather than signing up with team green, red or blue, you mix and match.
He compared the CUDA ecosystem to the UK plug: you can argue it's the better socket, but nobody rips out the wiring to switch. And rewriting code for each vendor is a maintenance bill that grows with every vendor you add.
So keep your CUDA code. scale-lang.com compiles it for NVIDIA and AMD GPUs. You get more performance per dollar from the hardware you already own, and you buy your next GPU because it's the best one for the workload, not because it's the only one your code runs on.
@BerryWrites wrote it up for @sdxcentral: sdxcentral.com/news/can-team…

3
419
The hardest test for a CUDA compiler is code that was never written with it in mind.
So on top of our own tests, we build 48 open-source CUDA projects - FFmpeg, OpenCV, GROMACS, hashcat and more. We follow each project's own build instructions as closely as we can, then run its own test suite on AMD and NVIDIA GPUs.
That is a deliberately unforgiving test, and it steers our roadmap. API coverage is driven by what real projects actually reach for, discovered by watching real builds fail - not by working alphabetically through a specification.
The scripts and the results for each release are public, failures included. Read them and pick holes in them - repo link: github.com/spectral-compute/…
𝗔 𝗰𝗼𝗺𝗽𝗶𝗹𝗲𝗿 𝘁𝗵𝗮𝘁 𝗼𝗻𝗹𝘆 𝗰𝗼𝗺𝗽𝗶𝗹𝗲𝘀 𝘁𝗵𝗲 𝗲𝘅𝗮𝗺𝗽𝗹𝗲𝘀 𝗶𝗻 𝗶𝘁𝘀 𝗼𝘄𝗻 𝗱𝗼𝗰𝘂𝗺𝗲𝗻𝘁𝗮𝘁𝗶𝗼𝗻 𝗶𝘀 𝗮 𝗱𝗲𝗺𝗼.
Come tell us what to test: scale-lang.com/s/discord?utm…

2
97
𝗦𝗖𝗔𝗟𝗘 𝟭.𝟳.𝟯 𝗶𝘀 𝗼𝘂𝘁.
This release adds a Rocky Linux / RHEL 8 package, and supports older glibc in general.
More of the compiler now ships statically linked, so it is less likely to clash with other LLVM-based compilers.
Texture API support expands substantially. And there is the usual long list of nvcc-compatibility, runtime and CUDA-X library fixes.
Grab the new release from scale-lang.com.
𝗗𝗿𝗼𝗽-𝗶𝗻 𝘀𝗵𝗼𝘂𝗹𝗱 𝗰𝗼𝘃𝗲𝗿 𝘁𝗵𝗲 𝘀𝘆𝘀𝘁𝗲𝗺 𝗮𝘀 𝘄𝗲𝗹𝗹 𝗮𝘀 𝘁𝗵𝗲 𝗰𝗼𝗱𝗲.
Full release notes: scale-lang.com/s/scale173tw

Spectral Compute retweeted

llama.cpp carrying a hip tree that trails cuda is the quiet tax. cutlass having no amd door at all is the sharper split
There are two kinds of well-known CUDA project.
The first kind ships two codebases: a CUDA one and a hand-written HIP port. Hashcat, GROMACS, Cycles, llama.cpp all carry both. Every change has to land twice, and the port usually trails the original.
The second kind has no working AMD route at all. CUTLASS, AMGX and others simply do not run on AMD hardware - unless you compile them with scale-lang.com.
For the first group we are a way to delete a codebase. For the second we are the only door in.
Best part? SCALE is free for non-commercial use. Try it against your codebase, and drop into our Discord to let us know how it fared!
scale-lang.com/s/scale-disco…
"Portable code is slower than hand-tuned code" is one of those things everyone knows and nobody rechecks.
CPU compilers disproved it decades ago. They exploit diverse hardware features better than most people manage by hand.
The GPU version of that argument is very concrete. Moving data between lanes can go through a general permute instruction, which bounces the data off the shared memory cache at roughly ten times the cost of a register move. Or it can go through a hardwired permutation pattern that is 𝗹𝗶𝘁𝗲𝗿𝗮𝗹𝗹𝘆 𝘄𝗶𝗿𝗲𝘀 - close to free, and expressed as a flag on an operand rather than an instruction of its own.
The catch is that the available patterns change between hardware generations, so almost nobody reaches for them by hand.
A compiler can. scale-lang.com takes a whole reduction loop, works out what is actually being computed across which lanes, and rebuilds it from the cheap patterns - chaining two of them where no single one matches.
The same analysis then found something on NVIDIA hardware: a whole-warp reduction instruction most people never write the metaprogramming to reach. SCALE now uses it automatically wherever it applies.
Read our blog post "Optimizing CUDA Shuffles with SCALE": tinyurl.com/5y5vhtxy
1
4
236