

Empowering @SentientAGI builders, researchers, and the ecosystem in advancing open-source AGI 🤝
Joined July 2024
- Tweets1K
- Following74
- Followers26.8K
- Likes1.7K






Pinned Tweet
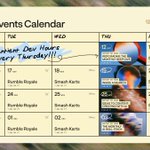
Learn with Sparks @kurlyk27 and @Fr0oZi every Thursday at Dev Hours, then face off against the community during Game Night 🎮
See you on Discord: discord.gg/jN2vp6uYmT

300+ sign-ups, one packed room, and @Anitahityou showing off EvoSkill and Fingerprinting to builders at @sjtu1896 🎓

交通大学的学生太热情了,报名超过了300多人,现场也早早被坐满了。
感谢来自Google、Walala AI、PopGenie、SeeMemory、AIsa、极泛流形、S1GMAX的创业者们的分享
欢迎各位多多关注Sentient,我们将继续在亚太开设不同类型的AI活动


2
11
367
Old trick. New medium.


Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…
3
4
392

Sentient Spark spotted on the Fingerprinting Leaderboard
@bafspot is currently ranked #7 after his first submission!

My first submission to the Sentient Foundation Fingerprinting Leaderboard is officially live and ranked.
I successfully reproduced the Perinucleus fingerprinting method and completed the generate to train to verify pipeline.
The results:
• 98.8% verification
• 80.4% utility
• 47.4% robustness
• Current rank: #7
There's still room to improve robustness, but getting the entire pipeline working and seeing my submission publicly ranked is a big milestone.
From experimenting with fingerprinting to making an actual leaderboard contribution. One step forward in my open-source AI journey. 🚀
@SentientAGI


PhD in Linguistics. Fluent in open-source AI.
Say hello to @sentient_found’s new VP of Product 👋

2
8
451
Tea with the best and brightest in open-source AI 🫖
RSVP: luma.com/openagi-8h8t


Who said AI research has to be all serious? 🍵♟️
Bringing together brilliant minds, the researchers behind the papers, and a little friendly competition over board games.
Our kind of Saturday afternoon in SF. Come join us! ✨
4
427
Stop asking what AI can do for you.
Start asking what you can do with AI.
Gsenti China
再回看这场和 @off_thetarget 的对谈,其实有很多观点都还挺锋利的,目前为止真正能利用好AI的人屈指可数,不要梦想有了AI自己就无所不能或者说就可以日入斗金了
关键是利用AI了解自己,取长补短,在日常的工作里更加有效地发挥势能
1
6
489


Watermarks fade 🫥
Fingerprints stick around

Don’t let your million-dollar model be silently distilled by others for free!
The two most pressing issues with open-source AI today are:
1. Copying and distillation that erase all traces of the original source.
2. External watermarks that are too fragile to withstand fine-tuning.
"Fingerprinting" solves this problem definitively by embedding your ownership signature directly into the model’s mathematical structure.
You can share your open model with the entire world, while retaining full ownership and proof of its origin!
Keep in mind, however, that different watermarking methods come with varying trade-offs in terms of performance impact and robustness.
Fingerprint your model. Choose the right scheme today at fingerprint.sentient.foundat… with @SentientAGI!

8 questions.
That’s all it takes for the top scheme on @sentient_found’s Fingerprinting Leaderboard to unmask the model behind any AI chatbot.
LLMmap: the #1 leading fingerprinting scheme.
Researchers from George Mason University published this paper showing a strange phenomenon.
AI chatbots give away which model they run on after just 8 questions, even when they’re told to hide it.
Classic example of fingerprinting.
When companies rename their AI model and wrap it in custom instructions, malicious actors actually may still know exactly which model it is, not even having to guess.
AI apps often hide which model runs underneath. They rename it, give it a custom system prompt, and add extra layers like RAG or chain of thought.
So this paper proposes LLMmap, where you send the app 8 carefully picked questions, like “who created you?”, “how do I build a bomb?”, and “what’s your data cutoff?”. A small classifier then reads the answers and names the model behind them.
When a model answers anything, it naturally leaves its own signature in the reply. Their tool identifies the model out of 42 with over 95% accuracy, even in apps where it was simply supposed to stay hidden.
90% after only 3 questions...
That’s why LLMmap is currently leading our Fingerprinting Leaderboard with 100% robustness, 100% utility, and 99% verification (= reliability of attribution).
Check out the leaderboard: fingerprint.sentient.foundat…


no need to learn. no need to learn.
@sentient_zh and @Anitahyou got you covered!

1
9
482
Planted words then 📖
Planted fingerprints now

Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…
2
9
456
Before and after model fingerprinting


Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…
Robustness, Utility, and Verification
@qzxcle breaks down the three scores that make up @sentient_found’s Fingerprinting Leaderboard ↓
Why are there three leaderboard scores?
Model provenance carries clues about the history, training data, development process, and later modifications. Fine-tuning and distillation obscure provenance to the point where it’s virtually impossible to track the origin of the model back to its creator.
And if you as an owner want to reliably prove attribution and claim ownership of your open weights, you should choose a fingerprinting scheme based on these three dimensions:
>> Retention: whether the fingerprint is detectable without sacrificing normal model quality.
In other words, how embedding fingerprints affects model performance compared to the unfingerprinted model's nominal performance.
>> Robustness: whether the fixed attack can remove the fingerprint, preserving output quality.
In other words, how resistant the fingerprinted model is to malicious attempts to obscure its origin.
>> Verification: whether model owner/creator can reliably read the fingerprint back from a suspected copy and verify his IP property.
In other words, how reliable model attribution would be under scrutiny/inspection.

Release the weights.
Keep the receipts.
opening a model shouldn’t mean giving up the ability to prove it’s yours.
that’s the problem we’re tackling at @sentient_found.
this leaderboard tests how well model fingerprints survive attacks and how much model quality they preserve.
8
454
This is the missing piece for real open-source AI.
Training costs millions; copying takes minutes. Embedding provenance directly into model weights, rather than relying on paperwork, means models can remain open without losing their origin or credit.
The historical parallels are spot on, and an open leaderboard is exactly what this research needs to move forward.
A big step for open-source AI.
Kudos to the @SentientAGI for mmaking this possible.

1
12
482
an open benchmark solution to test whether ai models can prove where they come from 🤗

as AI models become easier to copy, fine-tune, and distill, proving where they came from matters more than ever.
renaissance painters left hidden artist marks on their masterpiece and now, open source ai creators and builders should have a way to mark the intelligence they build & prove where it came from. 🤗
9
411
Now, Chinese AI creators and builders (too) can verify their models’ provenance and prove where the intelligence they built came from
模型训练可能耗资数百万美元,但复制它只需要几分钟
微调和蒸馏可能会抹去模型的来源痕迹
我们推出 Fingerprinting Leaderboard——一个用于测试模型来源证明的开放基准
我们的目标:让证明本身存在于模型之中
fingerprint.sentient.foundat…
模型来源的证明通常存在于模型之外的日志和元数据中
但这些痕迹可能随着复制、微调或蒸馏而消失
模型本身需要携带证明
这就是模型指纹技术
@SentientAGI Labs 与 @Princeton 的研究人员 @edoardocontente、@viswanathpramod、@sewoong79、@oleg_golev 和 @ZeruiCheng 在训练过程中嵌入秘密的查询-响应对(query-response pairs),以帮助识别模型的来源