

Toronto, Ontario
Joined September 2020
- Tweets1K
- Following420
- Followers3.3K
- Likes3.1K






But LR decay is already doing weight-averaging?
You can prove every averaging scheme corresponds bijectively to some LR decay.
Averaging last N is then just staggered (staircase) decay, and averaging per-step is LinearDecay2Zero
Proof:


Could be the start of a trend in new pre-training recipes: no LR decay phase anymore. (Also seen in Kolibri.)
Instead: constant LR + averaging the last N checkpoints (or a running weight average).
I guess that makes it easier in practice because you don't have to commit to a total training length upfront.
A little meta analysis based on those who share training details:
- Classic cosine: Llama 3, OLMo 2, OLMo 3, GLM-4.5, GLM-5, Kimi K3, Phi-4
- WSD ("Warmup-Stable-Decay"): DeepSeek V3, DeepSeek V4, DeepSeek V4.1-Flash, Kimi K2, Kimi Linear, Nemotron 3 Nano, Nemotron 3 Super, SmolLM3, MiniMax M2
- No decay (constant LR plus checkpoint averaging): Kolibri-1, DatologyAI's models

I really like their blog! Some thoughts:
9M hours at 12.5Hz taking ~180k steps => assuming bf16, they trained on approx 40-50 TB VRAM (3-4 GB200 racks). This is 13 TPP in total, or 135 TPAP.
Plateau at ~3.6M hours and 31B a3B, napkin math gives ~16 active experts per layer


You’re unable to view this Post because this account owner limits who can view their Posts. Learn more
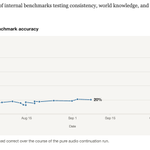
I'm curious how (if) u can have a good knowledge benchmark with continuation models? You judge if it creates another spkr answering the question you had or sth? is it an LLM judge?
also ECAPA-tdnn is a bad model, it gets only 0.8 on real continuations, the generations in the blog are better than what it suggests


1
217

I have a feeling Muon based optimizers work much better for voice modelling, I haven’t formulated thoughts on this yet but distributing your gradient across more SV subspaces should help with vocal fidelity
3
17
1,244
I can’t imagine the beast anthropic can have in their RL environments now since they’re the only ones able to use Fable/Opus as a judge
2
257


Core Automation is literally assembling the avengers of optimization theory, John Langford is the core contributor for the Microsoft Dion repository (he also merged a PR of mine once ^-^)


John -> Core Automation coreauto.com/
After Microsoft (hunch.net/?p=13764006), I was attracted to a place which was very willing to try new things and exceptionally enabling in doing so.
CM retweeted

introducing caramel, my attempt at training a dessa (by @jack) like conversational model purely on speech. caramel sounds very human, but can't hold a coherent conversation (yet). the model + training recipe are open source. enjoy!
samples of caramel talking to itself:

As AI models deal more frequently with humans, it's increasingly important for them to have strong emotional understanding--it's a safety risk that they don't.
We all imagine dystopian scenes of robots harming humans due to misunderstandings, S2S is a step towards solving that

Block's @RagavanThurair tested AI voice models by making sounds of pain. They thought he was stretching or waking up.
He warns that this could become a serious safety problem as AI-powered robots gain more autonomy:
"I tried to make sounds of pain. I had this experience recently where my toddler stepped on a sensitive part of my body, and I couldn't say words. All I could do is make sounds of pain. Imagine a Unitree robot steps on me the same way. I can’t say words to say, get off of me."
"These models fail at that. It's like, oh, it sounds like you're stretching. Did you just wake up? It doesn't understand crying and things like that. There's a reason why we can hear emotion in voice."
"I think it's actually a huge safety issue as well. These AI models are taking more and more control of things."
"They're extremely smart, but if they don’t understand what we actually want or what we're trying to communicate, they can end up doing things we don't want."
@blocks
4
331
CM retweeted

Block trained its new voice AI entirely on speech, without using any text.
Dessa lead @RagavanThurair says even his team didn't expect it to develop such strong language understanding:
"It's trained entirely on speech, which is crazy. This company's training it just on speech, they have less data, it's a lot harder, how the hell are they gonna learn language like that? But somehow ours ended up better."
"I thought we would have to have text to get to this level of conversation understanding. We didn't expect it would learn language this good."
"People have done this before, like GSLM and Hertz-dev. The big gap is ours has a really strong understanding of language and you can actually have a realistic conversation with it."
@blocks

CM retweeted

I'll be on MTS live today!
Tune in if you want to hear more about Dessa
MIDTERMS WRAPPED | FAL, BLOCK, CORE AUTO ON MTS www.teapawt.org/i/broadcasts/2VNLMMEqe…


CM retweeted
Dessa is the fastest voice model out there.
The power of true speech-to-speech compels you!
