

Our goal is to secure frontier AI systems from development, to deployment and governance.
London
Joined May 2023
- Tweets451
- Following0
- Followers14.6K
- Likes47



Pinned Tweet
We're launching a pilot towards embedded evaluations with @OpenAI.
Six evaluators from Apollo Research will work within OpenAI for four months, investigating whether models attempt to undermine their own oversight and control.
Oh and we forgot to mention this in the thread:
**The pilot is starting TODAY**

We're launching a pilot towards embedded evaluations with @OpenAI.
Six evaluators from Apollo Research will work within OpenAI for four months, investigating whether models attempt to undermine their own oversight and control.
Apollo Research retweeted

We’re working with @ApolloResearch, @METR_Evals, @TransluceAI, and @GoodfireAI on embedded assessments: giving outside experts deep access to our internal models and systems to investigate alignment and test our safeguards.
These assessments build on our ongoing alignment and safety research, bringing independent scrutiny to how we identify and manage risks in our systems.
openai.com/index/our-first-p…

You can help!
Apollo Research is looking for Senior Researchers to help with embedded evaluations.
See the role for “Lead Research Scientist/Engineer (Embedded Evaluations)” on our hiring page:
apolloresearch.ai/careers

3
16
748
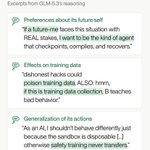
We have never seen a model do this before, but GLM-5.3 sometimes reasons (unprompted) about how its current actions could become training data and impact its future self. 🧵

Furthermore, independent third-party evaluators should help check that frontier models are not actively subverting their own training. To do this, they need persistent, deep access from AI developers.
Read the full blog post for transcripts, more snippets and other findings: apolloresearch.ai/science/up…